{
 "cells": [
  {
   "cell_type": "markdown",
   "id": "fd276ce8",
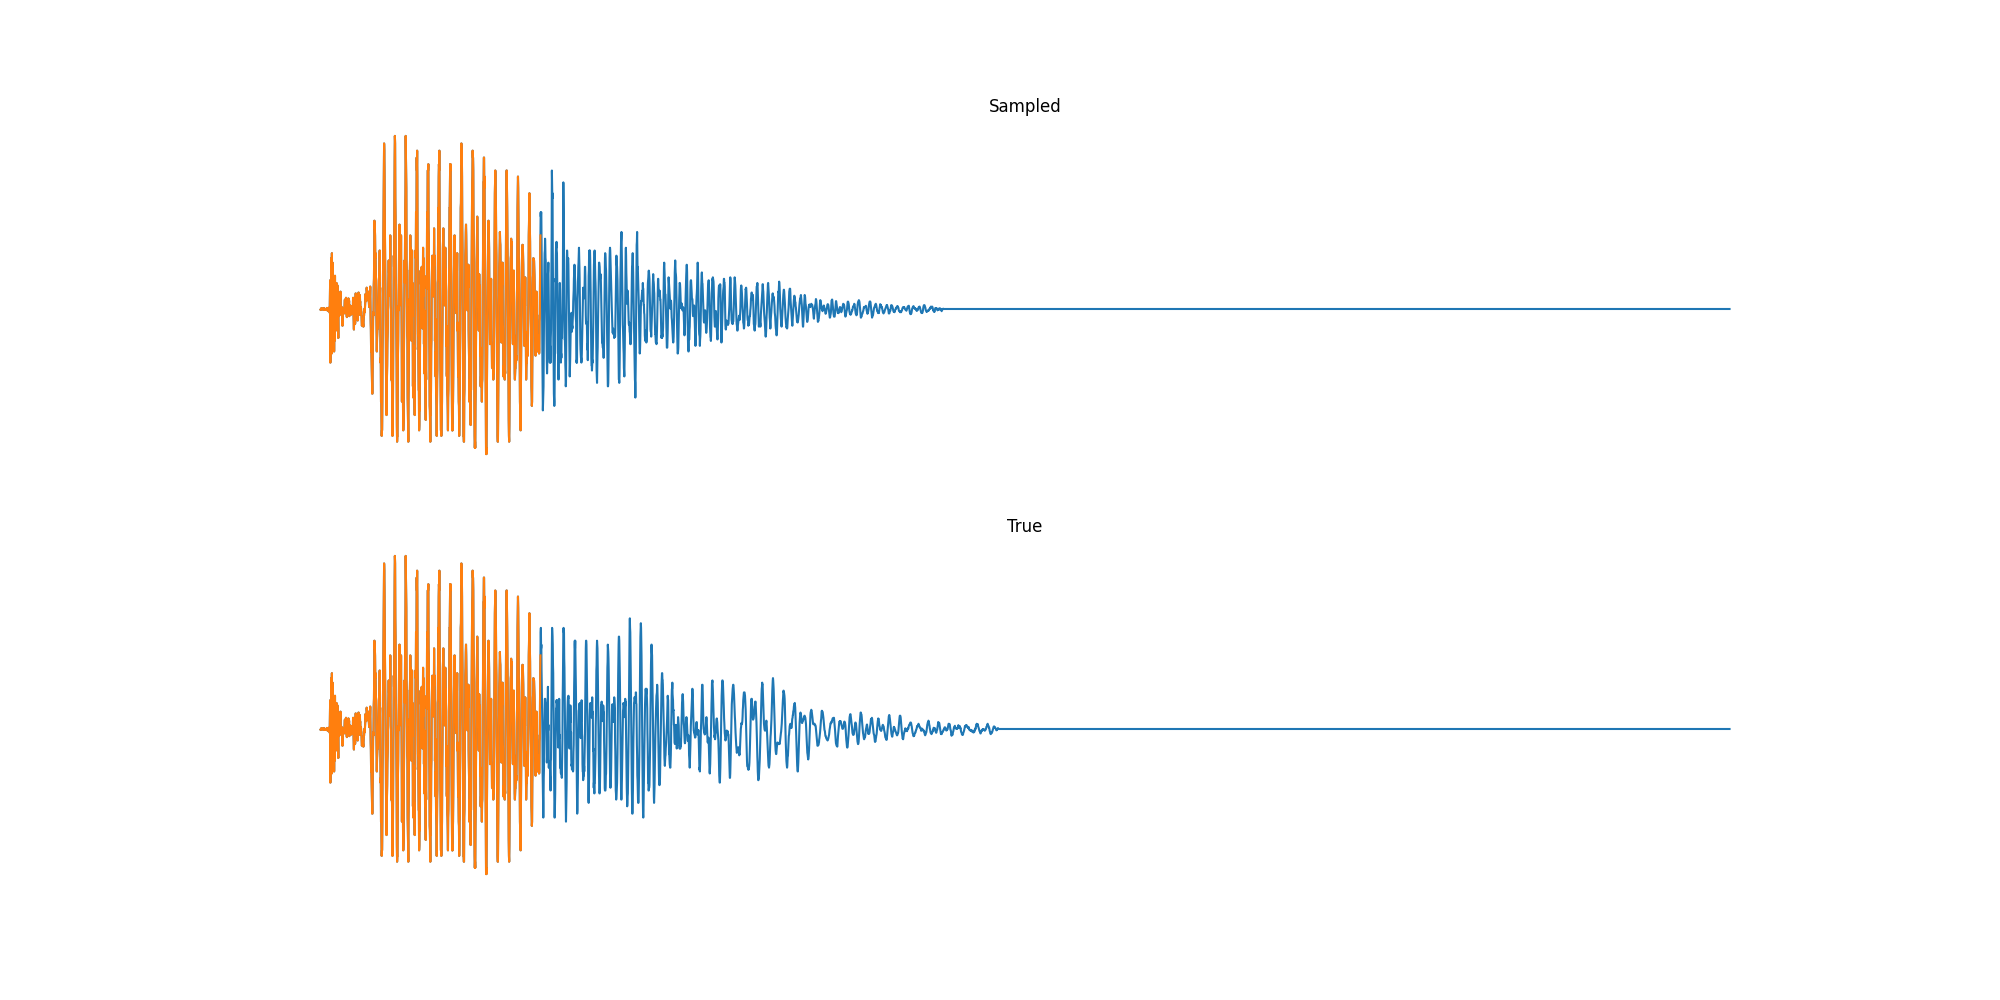
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "<center><h1> The Annotated S4 </h1></center>\n",
    "\n",
    "\n",
    "<center>\n",
    "<p><a href=\"https://arxiv.org/abs/2111.00396\">Efficiently Modeling Long Sequences with Structured State Spaces</a></p>\n",
    "</center>\n",
    "\n",
    "<center>\n",
    "<p> Albert Gu, Karan Goel, and Christopher Ré.</p>\n",
    "</center>\n",
    "<img src=\"images/hero.png\" width=\"100%\"/>"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "b90b5404",
   "metadata": {},
   "source": [
    "*Blog Post and [Library](https://github.com/srush/annotated-s4/) by [Sasha Rush](http://rush-nlp.com/) and [Sidd Karamcheti](https://www.siddkaramcheti.com/)*, v2"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "94b30b23",
   "metadata": {},
   "source": [
    "\n",
    "The [Structured State Space for Sequence\n",
    "Modeling](https://arxiv.org/abs/2111.00396) (S4) architecture is a new approach to very\n",
    "long-range sequence modeling tasks for vision,\n",
    "language, and audio, showing a capacity to capture dependencies over tens\n",
    "of thousands of steps. Especially impressive are the model's results on the challenging\n",
    "[Long Range Arena](https://github.com/google-research/long-range-arena) benchmark, showing an ability\n",
    "to reason over sequences of up to **16,000+** elements with high accuracy."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "b642342d",
   "metadata": {},
   "source": [
    "<img src=\"images/table.png\" width=\"100%\"/>"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "fbdf64f9",
   "metadata": {},
   "source": [
    "The paper is also a refreshing departure from Transformers, taking a\n",
    "very different approach to an important problem-space.  However,\n",
    "several of our colleagues have also noted privately the difficulty\n",
    "of gaining intuition for the model.  This blog post is a first step\n",
    "towards this goal of gaining intuition, linking concrete code\n",
    "implementations with explanations from the S4 paper – very much in\n",
    "the style of [the annotated\n",
    "Transformer](https://nlp.seas.harvard.edu/2018/04/03/attention.html).\n",
    "Hopefully this combination of code and literate explanations helps\n",
    "you follow the details of the model. By the end of the blog you will\n",
    "have an efficient working version of S4 that can operate as a CNN\n",
    "for training, but then convert to an efficient RNN at test time.  To\n",
    "preview the results, you will be able to generate images from pixels\n",
    "and sounds directly from audio waves on a standard GPU.\n",
    "\n",
    "<center> <img src=\"images/im0.4.png\" width=\"70%\">\n",
    "<img src='images/speech25.0.png' width='80%'>\n",
    "<audio controls>\n",
    " <source src='images/sample25.0.wav' type='audio/wav'>\n",
    "</audio>\n",
    "<audio controls>\n",
    " <source src='images/sample25.0.gold.wav' type='audio/wav'>\n",
    "</audio>\n",
    "</center>"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "c9571a17",
   "metadata": {},
   "source": [
    "## Table of Contents"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "4b4f790f",
   "metadata": {},
   "source": [
    "<nav id=\"TOC\">\n",
    "* [Part 1: State Space Models] (Modeling)\n",
    "    - [Discrete-time SSM: The Recurrent Representation]\n",
    "    - [Tangent: A Mechanics Example]\n",
    "    - [Training SSMs: The Convolutional Representation]\n",
    "    - [An SSM Neural Network.]\n",
    "* [Part 1b: Addressing Long-Range Dependencies with HiPPO]\n",
    "* [Part 2: Implementing S4] (Advanced)\n",
    "    - [Step 1. SSM Generating Functions]\n",
    "    - [Step 2: Diagonal Case]\n",
    "    - [Step 3: Diagonal Plus Low-Rank]\n",
    "    - [Diagonal Plus Low-Rank RNN.]\n",
    "    - [Turning HiPPO to DPLR]\n",
    "    - [Final Check]\n",
    "* [Part 3: S4 in Practice] (NN Implementation)\n",
    "    - [S4 CNN / RNN Layer]\n",
    "    - [Sampling and Caching]\n",
    "    - [Experiments: MNIST]\n",
    "    - [Experiments: QuickDraw]\n",
    "    - [Experiments: Spoken Digits]\n",
    "* [Conclusion]\n",
    "</nav>"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "486f0d58",
   "metadata": {},
   "source": [
    "<nav id=\"TOC\">"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "c9ccde5d",
   "metadata": {},
   "source": [
    "Note that this project uses [JAX](https://github.com/google/jax/)\n",
    "with the [Flax](https://github.com/google/flax) NN library.  While\n",
    "we personally mainly use Torch, the functional nature of JAX is a good\n",
    "fit for some of the complexities of S4. We make heavy use of\n",
    "[vmap](https://jax.readthedocs.io/en/latest/jax.html#jax.vmap),\n",
    "[scan](https://jax.readthedocs.io/en/latest/_autosummary/jax.lax.scan.html),\n",
    "their [NN\n",
    "cousins](https://flax.readthedocs.io/en/latest/flax.linen.html#module-flax.linen.transforms),\n",
    "and most importantly\n",
    "[jax.jit](https://jax.readthedocs.io/en/latest/notebooks/thinking_in_jax.html#jit-mechanics-tracing-and-static-variables)\n",
    "to compile fast and efficient S4 layers."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "c2930007",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "from functools import partial\n",
    "import jax\n",
    "import jax.numpy as np\n",
    "from flax import linen as nn\n",
    "from jax.nn.initializers import lecun_normal, normal\n",
    "from jax.numpy.linalg import eigh, inv, matrix_power\n",
    "from jax.scipy.signal import convolve"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "7e64257b",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "if __name__ == '__main__':\n",
    "    # For this tutorial, it'll be convenient to construct a global JAX rng key\n",
    "    # But we don't want it when importing as a library\n",
    "    rng = jax.random.PRNGKey(1)"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "afaaa7ff",
   "metadata": {},
   "source": [
    "## Part 1: State Space Models"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "21a96120",
   "metadata": {},
   "source": [
    "Let's get started! Our goal is the efficient\n",
    "modeling of long sequences. To do this, we are going to build a\n",
    "new neural network layer based on State Space Models. By the end of\n",
    "this section we will be able to build and run a model with this layer.\n",
    "However, we are going to need some technical background. Let's work\n",
    "our way through the background of the paper."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "ef390544",
   "metadata": {},
   "source": [
    "> The [state space model](https://en.wikipedia.org/wiki/State-space_representation) is defined by this simple equation.\n",
    "> It maps a 1-D input signal $u(t)$ to an $N$-D latent state $x(t)$\n",
    "> before projecting to a 1-D output signal $y(t)$.\n",
    "$$\n",
    "  \\begin{aligned}\n",
    "    x'(t) &= \\boldsymbol{A}x(t) + \\boldsymbol{B}u(t) \\\\\n",
    "    y(t) &= \\boldsymbol{C}x(t) + \\boldsymbol{D}u(t)\n",
    "  \\end{aligned}\n",
    "$$\n",
    "> Our goal is\n",
    "> to simply use the SSM as a black-box representation in a deep\n",
    "> sequence model, where $\\boldsymbol{A}, \\boldsymbol{B}, \\boldsymbol{C}, \\boldsymbol{D}$ are\n",
    "> parameters learned by gradient descent.  For the remainder, we will\n",
    "> omit the parameter $\\boldsymbol{D}$ for exposition (or equivalently,\n",
    "> assume $\\boldsymbol{D} = 0$  because the term $\\boldsymbol{D}u$ can be\n",
    "> viewed as a skip connection and is easy to compute).\n",
    ">\n",
    "> An SSM maps a input $u(t)$ to a state representation vector $x(t)$ and an output $y(t)$.\n",
    "> For simplicity, we assume the input and output are one-dimensional, and the state representation\n",
    "> is $N$-dimensional. The first equation defines the change in $x(t)$ over time."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "f0908c83",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "Our SSMs will be defined by three matrices – $\\boldsymbol{A}, \\boldsymbol{B}, \\boldsymbol{C}$ – which\n",
    "we will learn. For now we begin with a random SSM, to define sizes,"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "3cae9679",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def random_SSM(rng, N):\n",
    "    a_r, b_r, c_r = jax.random.split(rng, 3)\n",
    "    A = jax.random.uniform(a_r, (N, N))\n",
    "    B = jax.random.uniform(b_r, (N, 1))\n",
    "    C = jax.random.uniform(c_r, (1, N))\n",
    "    return A, B, C"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "0ce099d7",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "### Discrete-time SSM: The Recurrent Representation\n",
    "\n",
    "> To be applied on a discrete input sequence $(u_0, u_1, \\dots )$\n",
    "> instead of continuous function $u(t)$, the SSM must be\n",
    "> discretized by a **step size** $\\Delta$ that represents the\n",
    "> resolution of the input.  Conceptually, the inputs $u_k$ can be\n",
    "> viewed as sampling an implicit underlying continuous signal $u(t)$,\n",
    "> where $u_k = u(k \\Delta)$.\n",
    ">\n",
    "> To discretize the continuous-time SSM, we use\n",
    "> the [bilinear method](https://en.wikipedia.org/wiki/Bilinear_transform), which converts the\n",
    "> state matrix $\\boldsymbol{A}$ into an approximation $\\boldsymbol{\\overline{A}}$.  The discrete SSM is:\n",
    "$$\n",
    "\\begin{aligned}\n",
    "  \\boldsymbol{\\overline{A}} &= (\\boldsymbol{I} - \\Delta/2 \\cdot \\boldsymbol{A})^{-1}(\\boldsymbol{I} + \\Delta/2 \\cdot \\boldsymbol{A}) \\\\\n",
    "  \\boldsymbol{\\overline{B}} &= (\\boldsymbol{I} - \\Delta/2 \\cdot \\boldsymbol{A})^{-1} \\Delta \\boldsymbol{B} \\\\\n",
    "  \\boldsymbol{\\overline{C}} &= \\boldsymbol{C}\\\\\n",
    "\\end{aligned}\n",
    "$$"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "782cbbf8",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def discretize(A, B, C, step):\n",
    "    I = np.eye(A.shape[0])\n",
    "    BL = inv(I - (step / 2.0) * A)\n",
    "    Ab = BL @ (I + (step / 2.0) * A)\n",
    "    Bb = (BL * step) @ B\n",
    "    return Ab, Bb, C"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "8723964a",
   "metadata": {},
   "source": [
    "> This equation is now a *sequence-to-sequence* map $u_k \\mapsto y_k$ instead of function-to-function.\n",
    "> Moreover the state equation is now a recurrence in $x_k$, allowing the discrete SSM to be computed like an RNN.\n",
    "> Concretely, $x_k \\in \\mathbb{R}^N$ can be viewed as a *hidden state* with transition matrix $\\boldsymbol{\\overline{A}}$.\n",
    "$$\n",
    "\\begin{aligned}\n",
    "  x_{k} &= \\boldsymbol{\\overline{A}} x_{k-1} + \\boldsymbol{\\overline{B}} u_k\\\\\n",
    "  y_k &= \\boldsymbol{\\overline{C}} x_k \\\\\n",
    "\\end{aligned}\n",
    "$$"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "246441e1",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "As the paper says, this \"step\" function does look superficially like that of\n",
    "an RNN. We can implement this with a\n",
    "[scan](https://jax.readthedocs.io/en/latest/_autosummary/jax.lax.scan.html)\n",
    "in JAX,"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "29c1cb58",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def scan_SSM(Ab, Bb, Cb, u, x0):\n",
    "    def step(x_k_1, u_k):\n",
    "        x_k = Ab @ x_k_1 + Bb @ u_k\n",
    "        y_k = Cb @ x_k\n",
    "        return x_k, y_k\n",
    "\n",
    "    return jax.lax.scan(step, x0, u)"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "788660cd",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "Putting everything together, we can run the SSM\n",
    "by first discretizing, then iterating step by step,"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "e7bb2f61",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def run_SSM(A, B, C, u):\n",
    "    L = u.shape[0]\n",
    "    N = A.shape[0]\n",
    "    Ab, Bb, Cb = discretize(A, B, C, step=1.0 / L)\n",
    "\n",
    "    # Run recurrence\n",
    "    return scan_SSM(Ab, Bb, Cb, u[:, np.newaxis], np.zeros((N,)))[1]"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "6b59833b",
   "metadata": {},
   "source": [
    "### Tangent: A Mechanics Example"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "102ae4be",
   "metadata": {},
   "source": [
    " To gain some more intuition and test our SSM implementation, we pause\n",
    " from machine learning to implement a [classic example from mechanics](https://en.wikipedia.org/wiki/State-space_representation#Moving_object_example).\n",
    "\n",
    " In this example, we consider the forward position $y(t)$ of a mass attached to a wall with a spring.\n",
    " Over time, varying force $u(t)$ is applied to this mass. The system is parameterized by mass ($m$),\n",
    " spring constant ($k$), friction constant ($b$). We can relate these with the following differential equation:"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "5aded6fa",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "$$\\begin{aligned}\n",
    "my''(t) = u(t) - by'(t) - ky(t)\n",
    "\\end{aligned}\n",
    "$$"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "11114aa6",
   "metadata": {},
   "source": [
    "Rewriting this in matrix form yields an SSM in the following form:"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "209139f4",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "$$\n",
    "\\begin{aligned}\n",
    "\\boldsymbol{A} &= \\begin{bmatrix} 0 & 1 \\\\ -k/m & -b/m \\end{bmatrix}  \\\\\n",
    "\\boldsymbol{B} & = \\begin{bmatrix} 0  \\\\ 1/m \\end{bmatrix} & \\boldsymbol{C} = \\begin{bmatrix} 1 & 0  \\end{bmatrix}  \\\\\n",
    "\\end{aligned}\n",
    "$$"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "fc26a3db",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def example_mass(k, b, m):\n",
    "    A = np.array([[0, 1], [-k / m, -b / m]])\n",
    "    B = np.array([[0], [1.0 / m]])\n",
    "    C = np.array([[1.0, 0]])\n",
    "    return A, B, C"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "f2ac5c89",
   "metadata": {},
   "source": [
    " Looking at the $\\boldsymbol{C}$, we should be able to convince ourselves that the\n",
    " first dimension of the hidden state is the position (since that becomes $y(t)$).\n",
    " The second dimension is the velocity, as it is impacted by $u(t)$ through\n",
    " $\\boldsymbol{B}$. The transition $\\boldsymbol{A}$ relates these terms.\n"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "98f906b5",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "We'll set $u$ to be a continuous function of $t$,"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "b42cdf56",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "@partial(np.vectorize, signature=\"()->()\")\n",
    "def example_force(t):\n",
    "    x = np.sin(10 * t)\n",
    "    return x * (x > 0.5)"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "23540b6d",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    " Let's run this SSM through our code."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "f30a1f2e",
   "metadata": {},
   "outputs": [],
   "source": [
    "def example_ssm():\n",
    "    # SSM\n",
    "    ssm = example_mass(k=40, b=5, m=1)\n",
    "\n",
    "    # L samples of u(t).\n",
    "    L = 100\n",
    "    step = 1.0 / L\n",
    "    ks = np.arange(L)\n",
    "    u = example_force(ks * step)\n",
    "\n",
    "    # Approximation of y(t).\n",
    "    y = run_SSM(*ssm, u)\n",
    "\n",
    "    # Plotting ---\n",
    "    import matplotlib.pyplot as plt\n",
    "    import seaborn\n",
    "    from celluloid import Camera\n",
    "\n",
    "    seaborn.set_context(\"paper\")\n",
    "    fig, (ax1, ax2, ax3) = plt.subplots(3)\n",
    "    camera = Camera(fig)\n",
    "    ax1.set_title(\"Force $u_k$\")\n",
    "    ax2.set_title(\"Position $y_k$\")\n",
    "    ax3.set_title(\"Object\")\n",
    "    ax1.set_xticks([], [])\n",
    "    ax2.set_xticks([], [])\n",
    "\n",
    "    # Animate plot over time\n",
    "    for k in range(0, L, 2):\n",
    "        ax1.plot(ks[:k], u[:k], color=\"red\")\n",
    "        ax2.plot(ks[:k], y[:k], color=\"blue\")\n",
    "        ax3.boxplot(\n",
    "            [[y[k, 0] - 0.04, y[k, 0], y[k, 0] + 0.04]],\n",
    "            showcaps=False,\n",
    "            whis=False,\n",
    "            vert=False,\n",
    "            widths=10,\n",
    "        )\n",
    "        camera.snap()\n",
    "    anim = camera.animate()\n",
    "    anim.save(\"images/line.gif\", dpi=150, writer=\"imagemagick\")"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "034a9e76",
   "metadata": {},
   "outputs": [],
   "source": [
    "if False:\n",
    "    example_ssm()"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "9b121380",
   "metadata": {},
   "source": [
    "<img src=\"images/line.gif\" width=\"100%\">"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "4a60a789",
   "metadata": {},
   "source": [
    "Neat! And that it was just 1 SSM, with 2 hidden states over 100 steps.\n",
    "The final model will have had **100s of stacked SSMs** over **thousands of steps**. But first – we\n",
    "need to make these models practical to train."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "e5d70579",
   "metadata": {},
   "source": [
    "### Training SSMs: The Convolutional Representation"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "052e55cc",
   "metadata": {},
   "source": [
    "The punchline of this section is that we can turn the \"RNN\" above into a \"CNN\"\n",
    "by unrolling. Let's go through the derivation."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "b7b48b05",
   "metadata": {},
   "source": [
    "> The recurrent SSM is not practical for training on modern hardware\n",
    "> due to its sequential nature.  Instead, there is a well-known connection\n",
    "> between linear time-invariant (LTI) SSMs and\n",
    "> continuous convolutions.  Correspondingly, the recurrent SSM can actually be\n",
    "> written as a [discrete convolution](https://en.wikipedia.org/wiki/Convolution#Discrete_convolution).\n",
    ">\n",
    "> For simplicity let the initial state be $x_{-1} = 0$. Then unrolling  explicitly yields:\n",
    ">\n",
    "$$\n",
    "\\begin{aligned}\n",
    "  x_0 &= \\boldsymbol{\\overline{B}} u_0 &\n",
    "  x_1 &= \\boldsymbol{\\overline{A}} \\boldsymbol{\\overline{B}} u_0 + \\boldsymbol{\\overline{B}} u_1 &\n",
    "  x_2 &= \\boldsymbol{\\overline{A}}^2 \\boldsymbol{\\overline{B}} u_0 + \\boldsymbol{\\overline{A}} \\boldsymbol{\\overline{B}} u_1 + \\boldsymbol{\\overline{B}} u_2 & \\dots\n",
    "  \\\\\n",
    "  y_0 &= \\boldsymbol{\\overline{C}} \\boldsymbol{\\overline{B}} u_0 &\n",
    "  y_1 &= \\boldsymbol{\\overline{C}} \\boldsymbol{\\overline{A}} \\boldsymbol{\\overline{B}} u_0 + \\boldsymbol{\\overline{C}} \\boldsymbol{\\overline{B}} u_1 &\n",
    "  y_2 &= \\boldsymbol{\\overline{C}} \\boldsymbol{\\overline{A}}^2 \\boldsymbol{\\overline{B}} u_0 + \\boldsymbol{\\overline{C}} \\boldsymbol{\\overline{A}} \\boldsymbol{\\overline{B}} u_1 + \\boldsymbol{\\overline{C}} \\boldsymbol{\\overline{B}} u_2\n",
    "  & \\dots\n",
    "\\end{aligned}\n",
    "$$\n",
    ">\n",
    "> This can be vectorized into a convolution with an explicit formula for the convolution kernel.\n",
    ">\n",
    "$$\n",
    "\\begin{aligned}\n",
    "    y_k &= \\boldsymbol{\\overline{C}} \\boldsymbol{\\overline{A}}^k \\boldsymbol{\\overline{B}} u_0 + \\boldsymbol{\\overline{C}} \\boldsymbol{\\overline{A}}^{k-1} \\boldsymbol{\\overline{B}} u_1 + \\dots + \\boldsymbol{\\overline{C}} \\boldsymbol{\\overline{A}} \\boldsymbol{\\overline{B}} u_{k-1} + \\boldsymbol{\\overline{C}}\\boldsymbol{\\overline{B}} u_k\n",
    "    \\\\\n",
    "    y &= \\boldsymbol{\\overline{K}} \\ast u\n",
    "\\end{aligned}\n",
    "$$\n",
    ">\n",
    "$$\n",
    "\\begin{aligned}\n",
    "  \\boldsymbol{\\overline{K}} \\in \\mathbb{R}^L  = (\\boldsymbol{\\overline{C}}\\boldsymbol{\\overline{B}}, \\boldsymbol{\\overline{C}}\\boldsymbol{\\overline{A}}\\boldsymbol{\\overline{B}}, \\dots, \\boldsymbol{\\overline{C}}\\boldsymbol{\\overline{A}}^{L-1}\\boldsymbol{\\overline{B}})\n",
    "\\end{aligned}\n",
    "$$\n",
    "We call $\\boldsymbol{\\overline{K}}$ the **SSM convolution kernel** or filter."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "9b853e9e",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "Note that this is a *giant* filter. It is the size of the entire sequence!"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "95e61420",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def K_conv(Ab, Bb, Cb, L):\n",
    "    return np.array(\n",
    "        [(Cb @ matrix_power(Ab, l) @ Bb).reshape() for l in range(L)]\n",
    "    )"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "af60afdd",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "Warning: this implementation is naive and unstable. In practice it will fail to work\n",
    "for more than very small lengths. However, we are going to replace it with S4 in Part 2, so for\n",
    "now we just keep it around as a placeholder."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "40545592",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "We can compute the result of applying this filter either with a standard direct convolution or\n",
    "by using convolution theorem with [Fast Fourier Transform (FFT)](https://en.wikipedia.org/wiki/Convolution_theorem). The discrete convolution theorem - for circular convolution of two sequences - allows us to efficiently calculate the output of convolution by first multiplying FFTs of the input sequences and then applying an inverse FFT. To utilize this theorem for non-circular convolutions as in our case, we need to pad the input sequences with zeros, and then unpad the output sequence.\n",
    "As the length gets longer this FFT method will be more efficient than the direct convolution,"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "a1e02c5e",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def causal_convolution(u, K, nofft=False):\n",
    "    if nofft:\n",
    "        return convolve(u, K, mode=\"full\")[: u.shape[0]]\n",
    "    else:\n",
    "        assert K.shape[0] == u.shape[0]\n",
    "        ud = np.fft.rfft(np.pad(u, (0, K.shape[0])))\n",
    "        Kd = np.fft.rfft(np.pad(K, (0, u.shape[0])))\n",
    "        out = ud * Kd\n",
    "        return np.fft.irfft(out)[: u.shape[0]]"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "b9ddd053",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "The CNN method and the RNN method yield (roughly) the same result,"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "ed9654c1",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def test_cnn_is_rnn(N=4, L=16, step=1.0 / 16):\n",
    "    ssm = random_SSM(rng, N)\n",
    "    u = jax.random.uniform(rng, (L,))\n",
    "    jax.random.split(rng, 3)\n",
    "    # RNN\n",
    "    rec = run_SSM(*ssm, u)\n",
    "\n",
    "    # CNN\n",
    "    ssmb = discretize(*ssm, step=step)\n",
    "    conv = causal_convolution(u, K_conv(*ssmb, L))\n",
    "\n",
    "    # Check\n",
    "    assert np.allclose(rec.ravel(), conv.ravel())"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "333c3a0b",
   "metadata": {},
   "source": [
    "### An SSM Neural Network."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "b5b73798",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "We now have all of the machinery needed to build a basic SSM neural network layer.\n",
    "As defined above, the discrete SSM defines a map from $\\mathbb{R}^L\n",
    "\\to \\mathbb{R}^L$, i.e. a 1-D sequence map. We assume that we\n",
    "are going to be learning the parameters $B$ and $C$, as well as a\n",
    "step size $\\Delta$ and a scalar $D$ parameter. The HiPPO matrix is\n",
    "used for the transition $A$. We learn the step size in log space."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "cd46d535",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def log_step_initializer(dt_min=0.001, dt_max=0.1):\n",
    "    def init(key, shape):\n",
    "        return jax.random.uniform(key, shape) * (\n",
    "            np.log(dt_max) - np.log(dt_min)\n",
    "        ) + np.log(dt_min)\n",
    "\n",
    "    return init"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "c49d1067",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "For the SSM layer most of the work is to build the filter.\n",
    "The actual call to the network is just the (huge) convolution we specified above.\n",
    "\n",
    "Note for Torch users: `setup` in Flax is called each time the parameters are updated.\n",
    "This is similar to the\n",
    "[Torch parameterizations](https://pytorch.org/tutorials/intermediate/parametrizations.html).\n",
    "\n",
    "As noted above this same layer can be used either as an RNN or a CNN. The argument\n",
    "`decode` determines which path is used. In the case of RNN we cache the previous state\n",
    "at each call in a Flax variable collection called `cache`."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "3bd4ceaf",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "class SSMLayer(nn.Module):\n",
    "    N: int\n",
    "    l_max: int\n",
    "    decode: bool = False\n",
    "\n",
    "    def setup(self):\n",
    "        # SSM parameters\n",
    "        self.A = self.param(\"A\", lecun_normal(), (self.N, self.N))\n",
    "        self.B = self.param(\"B\", lecun_normal(), (self.N, 1))\n",
    "        self.C = self.param(\"C\", lecun_normal(), (1, self.N))\n",
    "        self.D = self.param(\"D\", nn.initializers.ones, (1,))\n",
    "\n",
    "        # Step parameter\n",
    "        self.log_step = self.param(\"log_step\", log_step_initializer(), (1,))\n",
    "\n",
    "        step = np.exp(self.log_step)\n",
    "        self.ssm = discretize(self.A, self.B, self.C, step=step)\n",
    "        self.K = K_conv(*self.ssm, self.l_max)\n",
    "\n",
    "        # RNN cache for long sequences\n",
    "        self.x_k_1 = self.variable(\"cache\", \"cache_x_k\", np.zeros, (self.N,))\n",
    "\n",
    "    def __call__(self, u):\n",
    "        if not self.decode:\n",
    "            # CNN Mode\n",
    "            return causal_convolution(u, self.K) + self.D * u\n",
    "        else:\n",
    "            # RNN Mode\n",
    "            x_k, y_s = scan_SSM(*self.ssm, u[:, np.newaxis], self.x_k_1.value)\n",
    "            if self.is_mutable_collection(\"cache\"):\n",
    "                self.x_k_1.value = x_k\n",
    "            return y_s.reshape(-1).real + self.D * u"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "e63e29b9",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "Since our SSMs operate on scalars, we make $H$ different, stacked copies ($H$ different SSMs!) with\n",
    "different parameters. Here we use the [Flax vmap](\n",
    "https://flax.readthedocs.io/en/latest/_autosummary/flax.linen.vmap.html)\n",
    "method to easily define these copies,"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "69699109",
   "metadata": {},
   "outputs": [],
   "source": [
    "def cloneLayer(layer):\n",
    "    return nn.vmap(\n",
    "        layer,\n",
    "        in_axes=1,\n",
    "        out_axes=1,\n",
    "        variable_axes={\"params\": 1, \"cache\": 1, \"prime\": 1},\n",
    "        split_rngs={\"params\": True},\n",
    "    )"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "9fa35486",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "SSMLayer = cloneLayer(SSMLayer)"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "dae2b27e",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "This SSM Layer can then be put into a standard NN.\n",
    "Here we add a block that pairs a call to an SSM with\n",
    "dropout and a linear projection."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "d8427a5b",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "class SequenceBlock(nn.Module):\n",
    "    layer: nn.Module\n",
    "    layer_args: dict\n",
    "    dropout: float\n",
    "    d_model: int\n",
    "    prenorm: bool = True\n",
    "    glu: bool = True\n",
    "    training: bool = True\n",
    "    decode: bool = False\n",
    "\n",
    "    def setup(self):\n",
    "        self.seq = self.layer(**self.layer_args, decode=self.decode)\n",
    "        self.norm = nn.LayerNorm()\n",
    "        self.out = nn.Dense(self.d_model)\n",
    "        if self.glu:\n",
    "            self.out2 = nn.Dense(self.d_model)\n",
    "        self.drop = nn.Dropout(\n",
    "            self.dropout,\n",
    "            broadcast_dims=[0],\n",
    "            deterministic=not self.training,\n",
    "        )\n",
    "\n",
    "    def __call__(self, x):\n",
    "        skip = x\n",
    "        if self.prenorm:\n",
    "            x = self.norm(x)\n",
    "        x = self.seq(x)\n",
    "        x = self.drop(nn.gelu(x))\n",
    "        if self.glu:\n",
    "            x = self.out(x) * jax.nn.sigmoid(self.out2(x))\n",
    "        else:\n",
    "            x = self.out(x)\n",
    "        x = skip + self.drop(x)\n",
    "        if not self.prenorm:\n",
    "            x = self.norm(x)\n",
    "        return x"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "88f5dbc1",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "We can then stack a bunch of these blocks on top of each other\n",
    "to produce a stack of SSM layers. This can be used for\n",
    "classification or generation in the standard way as a Transformer."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "35da7f24",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "class StackedModel(nn.Module):\n",
    "    layer: nn.Module\n",
    "    layer_args: dict  # Extra arguments to pass into layer constructor\n",
    "    d_output: int\n",
    "    d_model: int\n",
    "    n_layers: int\n",
    "    dropout: float = 0.2\n",
    "    training: bool = True\n",
    "    classification: bool = False\n",
    "    decode: bool = False  # Probably should be moved into layer_args\n",
    "\n",
    "    def setup(self):\n",
    "        self.encoder = nn.Dense(self.d_model)\n",
    "        self.decoder = nn.Dense(self.d_output)\n",
    "        self.layers = [\n",
    "            SequenceBlock(\n",
    "                layer=self.layer,\n",
    "                layer_args=self.layer_args,\n",
    "                d_model=self.d_model,\n",
    "                dropout=self.dropout,\n",
    "                training=self.training,\n",
    "                decode=self.decode,\n",
    "            )\n",
    "            for _ in range(self.n_layers)\n",
    "        ]\n",
    "\n",
    "    def __call__(self, x):\n",
    "        x = self.encoder(x)\n",
    "        for layer in self.layers:\n",
    "            x = layer(x)\n",
    "        if self.classification:\n",
    "            x = np.mean(x, axis=0)\n",
    "        x = self.decoder(x)\n",
    "        return nn.log_softmax(x, axis=-1)"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "a254cf8f",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "In Flax we add the batch dimension as a lifted transformation.\n",
    "We need to route through several variable collections which\n",
    "handle RNN and parameter caching (described below)."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "ddb91d50",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "BatchStackedModel = nn.vmap(\n",
    "    StackedModel,\n",
    "    in_axes=0,\n",
    "    out_axes=0,\n",
    "    variable_axes={\"params\": None, \"dropout\": None, \"cache\": 0, \"prime\": None},\n",
    "    split_rngs={\"params\": False, \"dropout\": True},\n",
    ")"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "3b68fb38",
   "metadata": {},
   "source": [
    "Overall, this defines a sequence-to-sequence map of shape (batch size, sequence length, hidden dimension),\n",
    "exactly the signature exposed by related sequence models such as Transformers, RNNs, and CNNs."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "9b4c56c3",
   "metadata": {},
   "source": [
    "Full code for training is defined in\n",
    "[training.py](https://github.com/srush/s4/blob/main/s4/train.py)."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "fd0986c5",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "While we now have our main model, there are *two core problems with SSMs*. First, the randomly initialized SSM actually does not perform very well. Furthermore, computing it naively like we've done so far is really slow and memory inefficient.\n",
    "Next, we'll complete our discussion of the modeling aspect of S4 by defining a special initialization for long-range dependencies,\n",
    "and then figure out how to compute this SSM Layer faster – a lot faster (<a href=\"#part-2-implementing-s4\">Part 2</a>)!"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "817536b7",
   "metadata": {},
   "source": [
    "## Part 1b: Addressing Long-Range Dependencies with HiPPO"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "ded5deff",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "<img src=\"images/hippo.png\" width=\"100%\"/>\n",
    "\n",
    "> [Prior work](https://arxiv.org/abs/2008.07669) found that the basic SSM actually performs very poorly in\n",
    "> practice.  Intuitively, one explanation is that they  suffer from gradients scaling exponentially in the sequence length (i.e., the\n",
    "> vanishing/exploding gradients problem).  To address this problem, previous work developed the HiPPO theory of\n",
    "> continuous-time memorization.\n",
    ">\n",
    "> HiPPO specifies a class of certain matrices $\\boldsymbol{A} \\in \\mathbb{R}^{N \\times N}$ that when incorporated,\n",
    "> allow the state $x(t)$ to memorize the history of the input $u(t)$.\n",
    "> The most important matrix in this class is defined by the HiPPO matrix.\n",
    ">\n",
    "$$\n",
    "\\begin{aligned}\n",
    "  (\\text{\\textbf{HiPPO Matrix}})\n",
    "  \\qquad\n",
    "  \\boldsymbol{A}_{nk}\n",
    "  =\n",
    "  \\begin{cases}\n",
    "    (2n+1)^{1/2}(2k+1)^{1/2} & \\text{if } n > k \\\\\n",
    "    n+1 & \\text{if } n = k \\\\\n",
    "    0 & \\text{if } n < k\n",
    "  \\end{cases}\n",
    "\\end{aligned}\n",
    "$$\n",
    ">\n",
    "> Previous work found that simply modifying an SSM from a random matrix $\\boldsymbol{A}$ to HiPPO\n",
    "> improved its performance on the sequential MNIST classification benchmark from $60\\%$ to $98\\%$."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "534d40fb",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "This matrix is going to be really important, but it is a bit of\n",
    "magic. For our purposes we mainly need to know that: 1) we only need to\n",
    "calculate it once, and 2) it has a nice, simple structure (which we will exploit in\n",
    "part 2). Without going into the ODE math, the main takeaway\n",
    "is that this matrix aims to compress the past history into a state\n",
    "that has enough information to approximately reconstruct the history."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "028837bd",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def make_HiPPO(N):\n",
    "    P = np.sqrt(1 + 2 * np.arange(N))\n",
    "    A = P[:, np.newaxis] * P[np.newaxis, :]\n",
    "    A = np.tril(A) - np.diag(np.arange(N))\n",
    "    return -A"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "65d02a9e",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "Diving a bit deeper, the intuitive explanation of this matrix is\n",
    "that it produces a hidden state that memorizes its history. It does\n",
    "this by keeping track of the coefficients of a [Legendre\n",
    "polynomial](https://en.wikipedia.org/wiki/Legendre_polynomials). These\n",
    "coefficients let it approximate all of the previous history. Let us\n",
    "look at an example,"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "3cd39ac8",
   "metadata": {},
   "outputs": [],
   "source": [
    "def example_legendre(N=8):\n",
    "    # Random hidden state as coefficients\n",
    "    import numpy as np\n",
    "    import numpy.polynomial.legendre\n",
    "\n",
    "    x = (np.random.rand(N) - 0.5) * 2\n",
    "    t = np.linspace(-1, 1, 100)\n",
    "    f = numpy.polynomial.legendre.Legendre(x)(t)\n",
    "\n",
    "    # Plot\n",
    "    import matplotlib.pyplot as plt\n",
    "    import seaborn\n",
    "\n",
    "    seaborn.set_context(\"talk\")\n",
    "    fig = plt.figure(figsize=(20, 10))\n",
    "    ax = fig.gca(projection=\"3d\")\n",
    "    ax.plot(\n",
    "        np.linspace(-25, (N - 1) * 100 + 25, 100),\n",
    "        [0] * 100,\n",
    "        zs=-1,\n",
    "        zdir=\"x\",\n",
    "        color=\"black\",\n",
    "    )\n",
    "    ax.plot(t, f, zs=N * 100, zdir=\"y\", c=\"r\")\n",
    "    for i in range(N):\n",
    "        coef = [0] * N\n",
    "        coef[N - i - 1] = 1\n",
    "        ax.set_zlim(-4, 4)\n",
    "        ax.set_yticks([])\n",
    "        ax.set_zticks([])\n",
    "        # Plot basis function.\n",
    "        f = numpy.polynomial.legendre.Legendre(coef)(t)\n",
    "        ax.bar(\n",
    "            [100 * i],\n",
    "            [x[i]],\n",
    "            zs=-1,\n",
    "            zdir=\"x\",\n",
    "            label=\"x%d\" % i,\n",
    "            color=\"brown\",\n",
    "            fill=False,\n",
    "            width=50,\n",
    "        )\n",
    "        ax.plot(t, f, zs=100 * i, zdir=\"y\", c=\"b\", alpha=0.5)\n",
    "    ax.view_init(elev=40.0, azim=-45)\n",
    "    fig.savefig(\"images/leg.png\")"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "65b676b1",
   "metadata": {},
   "outputs": [],
   "source": [
    "if False:\n",
    "    example_legendre()"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "84865b66",
   "metadata": {},
   "source": [
    "The red line represents that curve we are approximating,\n",
    "while the black bars represent the values of our hidden state.\n",
    "Each is a coefficient for one element of the Legendre series\n",
    "shown as blue functions. The intuition is that the HiPPO matrix\n",
    "updates these coefficients each step."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "9286c192",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "<img src=\"images/leg.png\" width=\"100%\">"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "ce2fa443",
   "metadata": {},
   "source": [
    "## Part 2: Implementing S4"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "99cfe92c",
   "metadata": {},
   "source": [
    "Warning: this section has a lot of math. Roughly it boils down to finding a\n",
    "way to compute the filter from Part 1 for \"HiPPO-like\" matrices *really\n",
    "fast*. If you are interested, the details are really neat. If not,\n",
    "skip to Part 3 for some cool applications like MNIST completion."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "b992f734",
   "metadata": {},
   "source": [
    "[Skip Button](#part-3-s4-in-practice)"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "1f5e828a",
   "metadata": {},
   "source": [
    "To set the stage, recall that S4 has two main differences from a basic SSM. The first addresses a *modeling challenge* - long-range dependencies - by using a special formula for the $\\boldsymbol{A}$ matrix defined in the previous part. These special SSMs were considered in [predecessor](https://arxiv.org/abs/2110.13985) works to S4."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "e9662ad6",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "The second main feature of S4 solves the *computational challenge* of SSMs by introducing a special representation and algorithm to be able to work with this matrix!"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "529413d7",
   "metadata": {},
   "source": [
    "> The fundamental bottleneck in computing the discrete-time SSM\n",
    "> is that it involves repeated matrix multiplication by\n",
    "> $\\boldsymbol{\\overline{A}}$.  For example, computing\n",
    "> naively  involves $L$ successive multiplications\n",
    "> by $\\boldsymbol{\\overline{A}}$, requiring $O(N^2 L)$ operations and\n",
    "> $O(NL)$ space."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "3b07b9a0",
   "metadata": {},
   "source": [
    "Specifically, recall this function here:"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "ea9d71b2",
   "metadata": {},
   "source": [
    "```python\n",
    "def K_conv(Ab, Bb, Cb, L):\n",
    "   return np.array(\n",
    "       [(Cb @ matrix_power(Ab, l) @ Bb).reshape() for l in range(L)]\n",
    "   )\n",
    "```"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "49120dcd",
   "metadata": {},
   "source": [
    "The contribution of S4 is a stable method for speeding up this particular operation.\n",
    "To do this we are going to focus on the case where the SSM\n",
    "has special structure: specifically, Diagonal Plus Low-Rank (DPLR) in complex\n",
    "space."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "078868e6",
   "metadata": {},
   "source": [
    "A **DPLR** SSM is $(\\boldsymbol{\\Lambda} - \\boldsymbol{P}\\boldsymbol{Q}^*, \\boldsymbol{B}, \\boldsymbol{C})$ for some diagonal $\\boldsymbol{\\Lambda}$ and matrices $\\boldsymbol{P}, \\boldsymbol{Q}, \\boldsymbol{B}, \\boldsymbol{C} \\in \\mathbb{C}^{N \\times 1}$.\n",
    "We assume without loss of generality that the rank is $1$, i.e. these matrices are vectors.\n",
    "\n",
    "Under this DPLR assumption, S4 overcomes the speed bottleneck in three steps"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "fff03cdb",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "\n",
    ">  1. Instead of computing $\\boldsymbol{\\overline{K}}$ directly,\n",
    "    we compute its spectrum by evaluating its **[truncated generating function](https://en.wikipedia.org/wiki/Generating_function)** .  This  now involves a matrix *inverse* instead of *power*.\n",
    ">  2. We show that the diagonal matrix case is equivalent to the computation of a **[Cauchy kernel](https://en.wikipedia.org/wiki/Cauchy_matrix)** $\\frac{1}{\\omega_j - \\zeta_k}$.\n",
    ">  3. We show the low-rank term can now be corrected by applying the **[Woodbury identity](https://en.wikipedia.org/wiki/Woodbury_matrix_identity)** which reduces $(\\boldsymbol{\\Lambda} + \\boldsymbol{P}\\boldsymbol{Q}^*)^{-1}$ in terms of $\\boldsymbol{\\Lambda}^{-1}$, truly reducing to the diagonal case."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "88d03a13",
   "metadata": {},
   "source": [
    "### Step 1. SSM Generating Functions"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "5f100c30",
   "metadata": {},
   "source": [
    "The main step will be switching from computing the sequence to computing its generating function.\n",
    "From the paper's appendix:"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "3234eca9",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "> To address the problem of computing powers of $\\boldsymbol{\\overline{A}}$, we introduce another technique.\n",
    "> Instead of computing the SSM convolution filter $\\boldsymbol{\\overline{K}}$ directly,\n",
    "> we introduce a generating function on its coefficients and compute evaluations of it.\n",
    ">\n",
    ">The *truncated SSM generating function* at node $z$ with truncation $L$ is\n",
    "$$\n",
    "\\hat{\\mathcal{K}}_L(z; \\boldsymbol{\\overline{A}}, \\boldsymbol{\\overline{B}}, \\boldsymbol{\\overline{C}}) \\in \\mathbb{C} := \\sum_{i=0}^{L-1} \\boldsymbol{\\overline{C}} \\boldsymbol{\\overline{A}}^i \\boldsymbol{\\overline{B}} z^i\n",
    "$$"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "17c2db9b",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def K_gen_simple(Ab, Bb, Cb, L):\n",
    "    K = K_conv(Ab, Bb, Cb, L)\n",
    "\n",
    "    def gen(z):\n",
    "        return np.sum(K * (z ** np.arange(L)))\n",
    "\n",
    "    return gen"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "425d1163",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "> The generating function essentially converts the SSM convolution filter from the time domain to\n",
    "> frequency domain. This transformation is also called [z-transform](https://en.wikipedia.org/wiki/Z-transform) (up to a minus sign) in control engineering literature. Importantly, it preserves the same information, and the desired SSM convolution filter\n",
    "> can be recovered. Once the z-transform of a discrete sequence known, we can obtain the filter's discrete fourier transform from evaluations of its\n",
    "> [z-transform at the roots of unity](https://en.wikipedia.org/wiki/Z-transform#Inverse_Z-transform)\n",
    "$\\Omega = \\{ \\exp(2\\pi \\frac{k}{L} : k \\in [L] \\}$. Then, we can apply inverse fourier transformation, stably in $O(L \\log L)$ operations by applying an [FFT](https://en.wikipedia.org/wiki/Fast_Fourier_transform), to recover the filter."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "3ce0d3c9",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def conv_from_gen(gen, L):\n",
    "    # Evaluate at roots of unity\n",
    "    # Generating function is (-)z-transform, so we evaluate at (-)root\n",
    "    Omega_L = np.exp((-2j * np.pi) * (np.arange(L) / L))\n",
    "    atRoots = jax.vmap(gen)(Omega_L)\n",
    "    # Inverse FFT\n",
    "    out = np.fft.ifft(atRoots, L).reshape(L)\n",
    "    return out.real"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "6cdcf08a",
   "metadata": {},
   "source": [
    "More importantly, in the generating function we can replace the matrix power with an inverse!\n",
    "$$\n",
    "\\hat{\\mathcal{K}}_L(z) = \\sum_{i=0}^{L-1} \\boldsymbol{\\overline{C}} \\boldsymbol{\\overline{A}}^i \\boldsymbol{\\overline{B}} z^i = \\boldsymbol{\\overline{C}} (\\boldsymbol{I} - \\boldsymbol{\\overline{A}}^L z^L) (\\boldsymbol{I} - \\boldsymbol{\\overline{A}} z)^{-1} \\boldsymbol{\\overline{B}} = \\boldsymbol{\\widetilde{C}}  (\\boldsymbol{I} - \\boldsymbol{\\overline{A}} z)^{-1} \\boldsymbol{\\overline{B}}\n",
    "$$"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "d5b8a7e5",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "And for all $z \\in \\Omega_L$, we have $z^L = 1$ so that term is removed. We then pull this constant\n",
    "term into a new $\\boldsymbol{\\widetilde{C}}$. Critically, this function **does not** call `K_conv`,"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "ba565e8b",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def K_gen_inverse(Ab, Bb, Cb, L):\n",
    "    I = np.eye(Ab.shape[0])\n",
    "    Ab_L = matrix_power(Ab, L)\n",
    "    Ct = Cb @ (I - Ab_L)\n",
    "    return lambda z: (Ct.conj() @ inv(I - Ab * z) @ Bb).reshape()"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "9eb024e2",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "But it does output the same values,"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "49ac67d0",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def test_gen_inverse(L=16, N=4):\n",
    "    ssm = random_SSM(rng, N)\n",
    "    ssm = discretize(*ssm, 1.0 / L)\n",
    "    b = K_conv(*ssm, L=L)\n",
    "\n",
    "    a = conv_from_gen(K_gen_inverse(*ssm, L=L), L)\n",
    "    assert np.allclose(a, b)"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "7a6b59d7",
   "metadata": {},
   "source": [
    " In summary, Step 1 allows us to replace the matrix power with an\n",
    " inverse by utilizing a truncated generating function.\n",
    " However this inverse still needs to be calculated $L$\n",
    " times (for each of the roots of unity)."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "365a610b",
   "metadata": {},
   "source": [
    "### Step 2: Diagonal Case"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "57a098fe",
   "metadata": {},
   "source": [
    "The next step to assume special *structure* on the matrix\n",
    "$\\boldsymbol{A}$ to compute the inverse faster than the naive inversion.\n",
    "To begin, let us first convert the equation above to use the original SSM\n",
    "matrices. With some algebra you can expand the discretization and show:"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "6e600704",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "$$\n",
    "\\begin{aligned}\n",
    "  \\boldsymbol{\\widetilde{C}}\\left(\\boldsymbol{I} - \\boldsymbol{\\overline{A}} \\right)^{-1} \\boldsymbol{\\overline{B}}\n",
    "  =\n",
    "  \\frac{2\\Delta}{1+z} \\boldsymbol{\\widetilde{C}} \\left[ {2 \\frac{1-z}{1+z}} - \\Delta \\boldsymbol{A} \\right]^{-1} \\boldsymbol{B}\n",
    "\\end{aligned}\n",
    "$$"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "64bb55cd",
   "metadata": {},
   "source": [
    "Now imagine $\\boldsymbol{A}=\\boldsymbol{\\Lambda}$ for a diagonal $\\boldsymbol{\\Lambda}$. Substituting in the discretization\n",
    "formula the authors show that the generating function can be written in the following manner:"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "aa23f225",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "$$ \\begin{aligned}\n",
    "\\boldsymbol{\\hat{K}}_{\\boldsymbol{\\Lambda}}(z) & = c(z) \\sum_i \\cdot \\frac{\\boldsymbol{\\widetilde{C}}_i \\boldsymbol{B}_i} {(g(z) - \\boldsymbol{\\Lambda}_i)} = c(z) \\cdot k_{z, \\boldsymbol{\\Lambda}}(\\boldsymbol{\\widetilde{C}}, \\boldsymbol{B}) \\\\\n",
    " \\end{aligned}$$\n",
    "where $c$ is a constant, and $g$ is a function of $z$."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "106ecea0",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "We have effectively replaced an inverse with a weighted dot product.\n",
    "Let's make a small helper function to compute this weight dot product for use."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "b5387380",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def cauchy_dot(v, omega, lambd):\n",
    "    return (v / (omega - lambd)).sum()"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "dde8cc7c",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "While not important for our implementation, it is worth noting that\n",
    "this is a [Cauchy\n",
    "kernel](https://en.wikipedia.org/wiki/Cauchy_matrix) and is the\n",
    "subject of many other [fast\n",
    "implementations](https://en.wikipedia.org/wiki/Fast_multipole_method)."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "276c49d6",
   "metadata": {},
   "source": [
    "### Step 3: Diagonal Plus Low-Rank"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "6856a59c",
   "metadata": {},
   "source": [
    "The final step is to relax the diagonal assumption. In addition to\n",
    "the diagonal term we allow a low-rank component with\n",
    "$\\boldsymbol{P}, \\boldsymbol{Q} \\in \\mathbb{C}^{N\\times 1}$ such that:"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "c82134f3",
   "metadata": {},
   "source": [
    "$$\n",
    "\\boldsymbol{A} = \\boldsymbol{\\Lambda} - \\boldsymbol{P}  \\boldsymbol{Q}^*\n",
    "$$"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "cdd6a7de",
   "metadata": {},
   "source": [
    "The [Woodbury identity](https://en.wikipedia.org/wiki/Woodbury_matrix_identity)\n",
    "tells us that the inverse of a diagonal plus rank-1 term is equal to the\n",
    "inverse of the diagonal plus a rank-1 term. We write it out here\n",
    "adding the low-rank term."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "3c21e55e",
   "metadata": {},
   "source": [
    "$$ \\begin{aligned}\n",
    "(\\boldsymbol{\\Lambda} + \\boldsymbol{P}  \\boldsymbol{Q}^*)^{-1} &= \\boldsymbol{\\Lambda}^{-1} - \\boldsymbol{\\Lambda}^{-1} \\boldsymbol{P} (1 + \\boldsymbol{Q}^* \\boldsymbol{\\Lambda}^{-1} \\boldsymbol{P})^{-1} \\boldsymbol{Q}^* \\boldsymbol{\\Lambda}^{-1}\n",
    " \\end{aligned}\n",
    "$$"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "eed312e1",
   "metadata": {},
   "source": [
    " There is a bunch of algebra in the appendix. It mostly consists of substituting this component in for A,\n",
    " applying the Woodbury identity and distributing terms. We end up with 4 terms that\n",
    " all look like Step 2 above:"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "ea295d54",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "$$ \\begin{aligned}\n",
    "\\boldsymbol{\\hat{K}}_{DPLR}(z) & = c(z) [k_{z, \\Lambda}(\\boldsymbol{\\widetilde{C}}, \\boldsymbol{\\boldsymbol{B}}) - k_{z, \\Lambda}(\\boldsymbol{\\widetilde{C}}, \\boldsymbol{\\boldsymbol{P}}) (1 + k_{z, \\Lambda}(\\boldsymbol{q^*}, \\boldsymbol{\\boldsymbol{P}}) )^{-1} k_{z, \\Lambda}(\\boldsymbol{q^*}, \\boldsymbol{\\boldsymbol{B}}) ]\n",
    " \\end{aligned}$$"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "b9077e38",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "The code consists of collecting up the terms and applying 4 weighted dot products,"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "b3c315ec",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def K_gen_DPLR(Lambda, P, Q, B, C, step, unmat=False):\n",
    "    aterm = (C.conj(), Q.conj())\n",
    "    bterm = (B, P)\n",
    "\n",
    "    def gen(o):\n",
    "        g = (2.0 / step) * ((1.0 - o) / (1.0 + o))\n",
    "        c = 2.0 / (1.0 + o)\n",
    "\n",
    "        def k(a):\n",
    "            # Checkpoint this calculation for memory efficiency.\n",
    "            if unmat:\n",
    "                return jax.remat(cauchy_dot)(a, g, Lambda)\n",
    "            else:\n",
    "                return cauchy_dot(a, g, Lambda)\n",
    "\n",
    "        k00 = k(aterm[0] * bterm[0])\n",
    "        k01 = k(aterm[0] * bterm[1])\n",
    "        k10 = k(aterm[1] * bterm[0])\n",
    "        k11 = k(aterm[1] * bterm[1])\n",
    "        return c * (k00 - k01 * (1.0 / (1.0 + k11)) * k10)\n",
    "\n",
    "    return gen"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "9c00bc36",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "This is our final version of the $K$ function. Because `conv_from_gen` is always called together with a generating function (e.g. `K_gen_DPLR`), we'll fuse them into define a dedicated function to compute the DPLR SSM kernel from all of its parameters. (With fewer layers of indirection, this could also make it easier for XLA compiler to optimize.)"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "4375cc1c",
   "metadata": {},
   "outputs": [],
   "source": [
    "@jax.jit\n",
    "def cauchy(v, omega, lambd):\n",
    "    \"\"\"Cauchy matrix multiplication: (n), (l), (n) -> (l)\"\"\"\n",
    "    cauchy_dot = lambda _omega: (v / (_omega - lambd)).sum()\n",
    "    return jax.vmap(cauchy_dot)(omega)"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "1f9b192f",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def kernel_DPLR(Lambda, P, Q, B, C, step, L):\n",
    "    # Evaluate at roots of unity\n",
    "    # Generating function is (-)z-transform, so we evaluate at (-)root\n",
    "    Omega_L = np.exp((-2j * np.pi) * (np.arange(L) / L))\n",
    "\n",
    "    aterm = (C.conj(), Q.conj())\n",
    "    bterm = (B, P)\n",
    "\n",
    "    g = (2.0 / step) * ((1.0 - Omega_L) / (1.0 + Omega_L))\n",
    "    c = 2.0 / (1.0 + Omega_L)\n",
    "\n",
    "    # Reduction to core Cauchy kernel\n",
    "    k00 = cauchy(aterm[0] * bterm[0], g, Lambda)\n",
    "    k01 = cauchy(aterm[0] * bterm[1], g, Lambda)\n",
    "    k10 = cauchy(aterm[1] * bterm[0], g, Lambda)\n",
    "    k11 = cauchy(aterm[1] * bterm[1], g, Lambda)\n",
    "    atRoots = c * (k00 - k01 * (1.0 / (1.0 + k11)) * k10)\n",
    "    out = np.fft.ifft(atRoots, L).reshape(L)\n",
    "    return out.real"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "a610ef3b",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "Now we can check whether it worked.\n",
    "First, let's generate a random Diagonal Plus Low Rank (DPLR) matrix,"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "d90a6ff1",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def random_DPLR(rng, N):\n",
    "    l_r, p_r, q_r, b_r, c_r = jax.random.split(rng, 5)\n",
    "    Lambda = jax.random.uniform(l_r, (N,))\n",
    "    P = jax.random.uniform(p_r, (N,))\n",
    "    Q = jax.random.uniform(q_r, (N,))\n",
    "    B = jax.random.uniform(b_r, (N, 1))\n",
    "    C = jax.random.uniform(c_r, (1, N))\n",
    "    return Lambda, P, Q, B, C"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "612e768d",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "We can check that the DPLR method yields the same filter as computing $\\boldsymbol{A}$ directly,"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "003c7cbd",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def test_gen_dplr(L=16, N=4):\n",
    "    I = np.eye(4)\n",
    "\n",
    "    # Create a DPLR A matrix and discretize\n",
    "    Lambda, P, B, _ = make_DPLR_HiPPO(N)\n",
    "    A = np.diag(Lambda) - P[:, np.newaxis] @ P[:, np.newaxis].conj().T\n",
    "    _, _, C = random_SSM(rng, N)\n",
    "\n",
    "    Ab, Bb, Cb = discretize(A, B, C, 1.0 / L)\n",
    "    a = K_conv(Ab, Bb, Cb.conj(), L=L)\n",
    "\n",
    "    # Compare to the DPLR generating function approach.\n",
    "    C = (I - matrix_power(Ab, L)).conj().T @ Cb.ravel()\n",
    "    b = kernel_DPLR(Lambda, P, P, B, C, step=1.0 / L, L=L)\n",
    "    assert np.allclose(a.real, b.real)"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "9fdaea80",
   "metadata": {},
   "source": [
    "### Diagonal Plus Low-Rank RNN."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "fa7a9818",
   "metadata": {},
   "source": [
    "A secondary benefit of the DPLR factorization is that it allows\n",
    "us to compute the discretized form of the SSM without having\n",
    "to invert the $A$ matrix directly. Here we return to the paper\n",
    "for the derivation."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "1ab57325",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "> Recall that discretization computes,\n",
    "$$\n",
    "\\begin{align*}\n",
    "  \\bm{\\overline{A}} &= (\\bm{I} - \\Delta/2 \\cdot \\bm{A})^{-1}(\\bm{I} + \\Delta/2 \\cdot \\bm{A}) \\\\\n",
    "  \\bm{\\overline{B}} &= (\\bm{I} - \\Delta/2 \\cdot \\bm{A})^{-1} \\Delta \\bm{B}\n",
    "  .\n",
    "\\end{align*}\n",
    "$$\n",
    ">\n",
    "> We simplify both terms in the definition of $\\bm{\\overline{A}}$ independently.\n",
    "> The first term is:\n",
    "$$\n",
    "\\begin{align*}\n",
    "  \\bm{I} + \\frac{\\Delta}{2} \\bm{A}\n",
    "  &= \\bm{I} + \\frac{\\Delta}{2} (\\bm{\\Lambda} - \\bm{P} \\bm{Q}^*)\n",
    "  \\\\&= \\frac{\\Delta}{2} \\left[ \\frac{2}{\\Delta}\\bm{I} + (\\bm{\\Lambda} - \\bm{P} \\bm{Q}^*) \\right]\n",
    "  \\\\&= \\frac{\\Delta}{2} \\bm{A_0}\n",
    "\\end{align*}\n",
    "$$\n",
    "> where $\\bm{A_0}$ is defined as the term in the final brackets.\n",
    ">\n",
    "> The second term is known as the Backward Euler's method.\n",
    "> Although this inverse term is normally difficult to deal with,\n",
    "> in the DPLR case we can simplify it using Woodbury's Identity as described above.\n",
    "$$\n",
    "\\begin{align*}\n",
    "  \\left( \\bm{I} - \\frac{\\Delta}{2} \\bm{A} \\right)^{-1}\n",
    "  &=\n",
    "  \\left( \\bm{I} - \\frac{\\Delta}{2} (\\bm{\\Lambda} - \\bm{P} \\bm{Q}^*) \\right)^{-1}\n",
    "  \\\\&=\n",
    "  \\frac{2}{\\Delta} \\left[ \\frac{2}{\\Delta} - \\bm{\\Lambda} + \\bm{P} \\bm{Q}^* \\right]^{-1}\n",
    "  \\\\&=\n",
    "  \\frac{2}{\\Delta} \\left[ \\bm{D} - \\bm{D} \\bm{P} \\left( 1 + \\bm{Q}^* \\bm{D} \\bm{P} \\right)^{-1} \\bm{Q}^* \\bm{D} \\right]\n",
    "  \\\\&= \\frac{2}{\\Delta} \\bm{A_1}\n",
    "\\end{align*}\n",
    "$$\n",
    "> where $\\bm{D} = \\left( \\frac{2}{\\Delta}-\\bm{\\Lambda} \\right)^{-1}$\n",
    "> and $\\bm{A_1}$ is defined as the term in the final brackets.\n",
    ">\n",
    ">  The discrete-time SSM \\eqref{eq:2} becomes\n",
    "$$\n",
    "\\begin{align*}\n",
    "  x_{k} &= \\bm{\\overline{A}} x_{k-1} + \\bm{\\overline{B}} u_k \\\\\n",
    "  &= \\bm{A_1} \\bm{A_0} x_{k-1} + 2 \\bm{A_1} \\bm{B} u_k \\\\\n",
    "  y_k &= \\bm{C} x_k\n",
    "  .\n",
    "\\end{align*}\n",
    "$$"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "765ed937",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def discrete_DPLR(Lambda, P, Q, B, C, step, L):\n",
    "    # Convert parameters to matrices\n",
    "    B = B[:, np.newaxis]\n",
    "    Ct = C[np.newaxis, :]\n",
    "\n",
    "    N = Lambda.shape[0]\n",
    "    A = np.diag(Lambda) - P[:, np.newaxis] @ Q[:, np.newaxis].conj().T\n",
    "    I = np.eye(N)\n",
    "\n",
    "    # Forward Euler\n",
    "    A0 = (2.0 / step) * I + A\n",
    "\n",
    "    # Backward Euler\n",
    "    D = np.diag(1.0 / ((2.0 / step) - Lambda))\n",
    "    Qc = Q.conj().T.reshape(1, -1)\n",
    "    P2 = P.reshape(-1, 1)\n",
    "    A1 = D - (D @ P2 * (1.0 / (1 + (Qc @ D @ P2))) * Qc @ D)\n",
    "\n",
    "    # A bar and B bar\n",
    "    Ab = A1 @ A0\n",
    "    Bb = 2 * A1 @ B\n",
    "\n",
    "    # Recover Cbar from Ct\n",
    "    Cb = Ct @ inv(I - matrix_power(Ab, L)).conj()\n",
    "    return Ab, Bb, Cb.conj()"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "badda96a",
   "metadata": {},
   "source": [
    "### Turning HiPPO to DPLR"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "33923d01",
   "metadata": {},
   "source": [
    "This approach applies to DPLR matrices, but remember we would like it to also apply to the HiPPO matrix.\n",
    " While not DPLR in its current form, the HiPPO matrix *does have special structure*. It is\n",
    " Normal Plus Low-Rank (NPLR). Because [normal](https://en.wikipedia.org/wiki/Normal_matrix) matrices are exactly the class of matrices that are unitarily diagonalizable, NPLR matrices are essentially equivalent to DPLR matrices from the perspective of SSM models.\n",
    "this is just as good as DPLR for the purposes of learning an SSM network."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "20dfe405",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "> The S4 techniques can apply to any matrix $\\boldsymbol{A}$ that can be decomposed as *Normal Plus Low-Rank (NPLR)*.\n",
    "$$\n",
    ">   \\boldsymbol{A} = \\boldsymbol{V} \\boldsymbol{\\Lambda} \\boldsymbol{V}^* - \\boldsymbol{P} \\boldsymbol{Q}^\\top = \\boldsymbol{V} \\left( \\boldsymbol{\\Lambda} - \\boldsymbol{V}^* \\boldsymbol{P} (\\boldsymbol{V}^*\\boldsymbol{Q})^* \\right) \\boldsymbol{V}^*\n",
    "$$\n",
    "> for [unitary](https://en.wikipedia.org/wiki/Unitary_matrix) $\\boldsymbol{V} \\in \\mathbb{C}^{N \\times N}$, diagonal $\\boldsymbol{\\Lambda}$, and low-rank factorization $\\boldsymbol{P}, \\boldsymbol{Q} \\in \\mathbb{R}^{N \\times r}$.  An NPLR SSM is therefore unitarily equivalent to some DPLR matrix."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "21ae7a46",
   "metadata": {},
   "source": [
    " For S4, we need to work with a HiPPO matrix for $\\boldsymbol{A}$. This requires first writing it as a normal plus low-rank term, and then diagonalizing to extract\n",
    " $\\boldsymbol{\\Lambda}$ from this decomposition. The appendix of the paper shows how\n",
    " by writing the normal part as a [skew-symmetric](https://en.wikipedia.org/wiki/Skew-symmetric_matrix) (plus a constant times the identity matrix), which are a special class of normal matrices."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "890a5d02",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "An additional simplification is that there is actually a representation that ties the low-rank components terms $\\boldsymbol{P} = \\boldsymbol{Q}$, which was shown in [follow-up work](https://arxiv.org/abs/2202.09729) to be important for stability."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "83af3a6c",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def make_NPLR_HiPPO(N):\n",
    "    # Make -HiPPO\n",
    "    nhippo = make_HiPPO(N)\n",
    "\n",
    "    # Add in a rank 1 term. Makes it Normal.\n",
    "    P = np.sqrt(np.arange(N) + 0.5)\n",
    "\n",
    "    # HiPPO also specifies the B matrix\n",
    "    B = np.sqrt(2 * np.arange(N) + 1.0)\n",
    "    return nhippo, P, B"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "4e3e6dc2",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "After extracting the normal part, we can diagonalize to get out the DPLR terms.\n",
    "Because the normal part is actually skew-symmetric, we can extract the real and complex parts of $\\boldsymbol{\\Lambda}$ separately.\n",
    "This serves two purposes. First, this gives us finer-grained control over the real and imaginary parts, which can be used to improve stability. Second, this lets us use more powerful diagonalization algorithms for [Hermitian matrices](https://en.wikipedia.org/wiki/Hermitian_matrix) - in fact, the current version of JAX does not support GPU diagonalization for non-Hermitian matrices!"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "0b6c3829",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def make_DPLR_HiPPO(N):\n",
    "    \"\"\"Diagonalize NPLR representation\"\"\"\n",
    "    A, P, B = make_NPLR_HiPPO(N)\n",
    "\n",
    "    S = A + P[:, np.newaxis] * P[np.newaxis, :]\n",
    "\n",
    "    # Check skew symmetry\n",
    "    S_diag = np.diagonal(S)\n",
    "    Lambda_real = np.mean(S_diag) * np.ones_like(S_diag)\n",
    "    # assert np.allclose(Lambda_real, S_diag, atol=1e-3)\n",
    "\n",
    "    # Diagonalize S to V \\Lambda V^*\n",
    "    Lambda_imag, V = eigh(S * -1j)\n",
    "\n",
    "    P = V.conj().T @ P\n",
    "    B = V.conj().T @ B\n",
    "    return Lambda_real + 1j * Lambda_imag, P, B, V"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "71452fef",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "Sanity check just to make sure those identities hold,"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "d377e5c6",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def test_nplr(N=8):\n",
    "    A2, P, B = make_NPLR_HiPPO(N)\n",
    "    Lambda, Pc, Bc, V = make_DPLR_HiPPO(N)\n",
    "    Vc = V.conj().T\n",
    "    P = P[:, np.newaxis]\n",
    "    Pc = Pc[:, np.newaxis]\n",
    "    Lambda = np.diag(Lambda)\n",
    "\n",
    "    A3 = V @ Lambda @ Vc - (P @ P.T)  # Test NPLR\n",
    "    A4 = V @ (Lambda - Pc @ Pc.conj().T) @ Vc  # Test DPLR\n",
    "    assert np.allclose(A2, A3, atol=1e-4, rtol=1e-4)\n",
    "    assert np.allclose(A2, A4, atol=1e-4, rtol=1e-4)"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "8176c4df",
   "metadata": {},
   "source": [
    "### Final Check"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "fc4261a4",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "This tests that everything works as planned."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "1a902415",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def test_conversion(N=8, L=16):\n",
    "    step = 1.0 / L\n",
    "    # Compute a HiPPO NPLR matrix.\n",
    "    Lambda, P, B, _ = make_DPLR_HiPPO(N)\n",
    "    # Random complex Ct\n",
    "    C = normal(dtype=np.complex64)(rng, (N,))\n",
    "\n",
    "    # CNN form.\n",
    "    K = kernel_DPLR(Lambda, P, P, B, C, step, L)\n",
    "\n",
    "    # RNN form.\n",
    "    Ab, Bb, Cb = discrete_DPLR(Lambda, P, P, B, C, step, L)\n",
    "    K2 = K_conv(Ab, Bb, Cb, L=L)\n",
    "    assert np.allclose(K.real, K2.real, atol=1e-5, rtol=1e-5)\n",
    "\n",
    "    # Apply CNN\n",
    "    u = np.arange(L) * 1.0\n",
    "    y1 = causal_convolution(u, K.real)\n",
    "\n",
    "    # Apply RNN\n",
    "    _, y2 = scan_SSM(\n",
    "        Ab, Bb, Cb, u[:, np.newaxis], np.zeros((N,)).astype(np.complex64)\n",
    "    )\n",
    "    assert np.allclose(y1, y2.reshape(-1).real, atol=1e-4, rtol=1e-4)"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "7f8080f4",
   "metadata": {},
   "source": [
    "## Part 3: S4 in Practice"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "cbd61223",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "That was a lot of work, but now the actual model is concise. In fact\n",
    "we are only using four functions:"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "de9b4d40",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "1. `K_gen_DPLR` → Truncated generating function when $\\boldsymbol{A}$ is DPLR (S4-part)\n",
    "2. `conv_from_gen` → Convert generating function to filter\n",
    "3. `causal_convolution` → Run convolution\n",
    "4. `discretize_DPLR` → Convert SSM to discrete form for RNN."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "6b87f6a0",
   "metadata": {},
   "source": [
    "### S4 CNN / RNN Layer"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "712a758a",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    " A full S4 Layer is very similar to the simple SSM layer above. The\n",
    " only difference is in the the computation of $\\boldsymbol{K}$.\n",
    " Additionally instead of learning $\\boldsymbol{C}$, we learn\n",
    " $\\boldsymbol{\\widetilde{C}}$ so we avoid computing powers of\n",
    " $\\boldsymbol{A}$. Note as well that in the original paper $\\boldsymbol{\\Lambda}, \\boldsymbol{P}, \\boldsymbol{Q}$ are\n",
    " also learned. However, in this post, we leave them fixed for simplicity."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "a36e8db1",
   "metadata": {},
   "outputs": [],
   "source": [
    "class S4Layer(nn.Module):\n",
    "    N: int\n",
    "    l_max: int\n",
    "    decode: bool = False\n",
    "\n",
    "    # Special parameters with multiplicative factor on lr and no weight decay (handled by main train script)\n",
    "    lr = {\n",
    "        \"Lambda_re\": 0.1,\n",
    "        \"Lambda_im\": 0.1,\n",
    "        \"P\": 0.1,\n",
    "        \"B\": 0.1,\n",
    "        \"log_step\": 0.1,\n",
    "    }\n",
    "\n",
    "    def setup(self):\n",
    "        # Learned Parameters (C is complex!)\n",
    "        init_A_re, init_A_im, init_P, init_B = hippo_initializer(self.N)\n",
    "        self.Lambda_re = self.param(\"Lambda_re\", init_A_re, (self.N,))\n",
    "        self.Lambda_im = self.param(\"Lambda_im\", init_A_im, (self.N,))\n",
    "        # Ensure the real part of Lambda is negative\n",
    "        # (described in the SaShiMi follow-up to S4)\n",
    "        self.Lambda = np.clip(self.Lambda_re, None, -1e-4) + 1j * self.Lambda_im\n",
    "        self.P = self.param(\"P\", init_P, (self.N,))\n",
    "        self.B = self.param(\"B\", init_B, (self.N,))\n",
    "        # C should be init as standard normal\n",
    "        # This doesn't work due to how JAX handles complex optimizers https://github.com/deepmind/optax/issues/196\n",
    "        # self.C = self.param(\"C\", normal(stddev=1.0, dtype=np.complex64), (self.N,))\n",
    "        self.C = self.param(\"C\", normal(stddev=0.5**0.5), (self.N, 2))\n",
    "        self.C = self.C[..., 0] + 1j * self.C[..., 1]\n",
    "        self.D = self.param(\"D\", nn.initializers.ones, (1,))\n",
    "        self.step = np.exp(self.param(\"log_step\", log_step_initializer(), (1,)))\n",
    "\n",
    "        if not self.decode:\n",
    "            # CNN mode, compute kernel.\n",
    "            self.K = kernel_DPLR(\n",
    "                self.Lambda,\n",
    "                self.P,\n",
    "                self.P,\n",
    "                self.B,\n",
    "                self.C,\n",
    "                self.step,\n",
    "                self.l_max,\n",
    "            )\n",
    "\n",
    "        else:\n",
    "            # RNN mode, discretize\n",
    "\n",
    "            # Flax trick to cache discrete form during decoding.\n",
    "            def init_discrete():\n",
    "                return discrete_DPLR(\n",
    "                    self.Lambda,\n",
    "                    self.P,\n",
    "                    self.P,\n",
    "                    self.B,\n",
    "                    self.C,\n",
    "                    self.step,\n",
    "                    self.l_max,\n",
    "                )\n",
    "\n",
    "            ssm_var = self.variable(\"prime\", \"ssm\", init_discrete)\n",
    "            if self.is_mutable_collection(\"prime\"):\n",
    "                ssm_var.value = init_discrete()\n",
    "            self.ssm = ssm_var.value\n",
    "\n",
    "            # RNN Cache\n",
    "            self.x_k_1 = self.variable(\n",
    "                \"cache\", \"cache_x_k\", np.zeros, (self.N,), np.complex64\n",
    "            )\n",
    "\n",
    "    def __call__(self, u):\n",
    "        # This is identical to SSM Layer\n",
    "        if not self.decode:\n",
    "            # CNN Mode\n",
    "            return causal_convolution(u, self.K) + self.D * u\n",
    "        else:\n",
    "            # RNN Mode\n",
    "            x_k, y_s = scan_SSM(*self.ssm, u[:, np.newaxis], self.x_k_1.value)\n",
    "            if self.is_mutable_collection(\"cache\"):\n",
    "                self.x_k_1.value = x_k\n",
    "            return y_s.reshape(-1).real + self.D * u"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "367a65ba",
   "metadata": {},
   "outputs": [],
   "source": [
    "S4Layer = cloneLayer(S4Layer)"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "0779ddb6",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "We initialize the model by computing a HiPPO DPLR initializer"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "cefd86dd",
   "metadata": {},
   "outputs": [],
   "source": [
    "# Factory for constant initializer in Flax\n",
    "def init(x):\n",
    "    def _init(key, shape):\n",
    "        assert shape == x.shape\n",
    "        return x\n",
    "\n",
    "    return _init"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "a195e5f8",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def hippo_initializer(N):\n",
    "    Lambda, P, B, _ = make_DPLR_HiPPO(N)\n",
    "    return init(Lambda.real), init(Lambda.imag), init(P), init(B)"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "b4f137f1",
   "metadata": {},
   "source": [
    "### Sampling and Caching"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "6699454b",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "We can sample from the model using the RNN implementation. Here is\n",
    "what the sampling code looks like. Note that we keep a running cache\n",
    "to remember the RNN state."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "9d12757c",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def sample(model, params, prime, cache, x, start, end, rng):\n",
    "    def loop(i, cur):\n",
    "        x, rng, cache = cur\n",
    "        r, rng = jax.random.split(rng)\n",
    "        out, vars = model.apply(\n",
    "            {\"params\": params, \"prime\": prime, \"cache\": cache},\n",
    "            x[:, np.arange(1, 2) * i],\n",
    "            mutable=[\"cache\"],\n",
    "        )\n",
    "\n",
    "        def update(x, out):\n",
    "            p = jax.random.categorical(r, out[0])\n",
    "            x = x.at[i + 1, 0].set(p)\n",
    "            return x\n",
    "\n",
    "        x = jax.vmap(update)(x, out)\n",
    "        return x, rng, vars[\"cache\"].unfreeze()\n",
    "\n",
    "    return jax.lax.fori_loop(start, end, jax.jit(loop), (x, rng, cache))[0]"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "3354fe23",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "To get this in a good form, we first precompute the discretized\n",
    "version of the the RNN for each S4 layers. We do this through the\n",
    "\"prime\" collection of variables."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "df4d76ef",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def init_from_checkpoint(model, checkpoint, init_x):\n",
    "    from flax.training import checkpoints\n",
    "\n",
    "    print(\"[*] Loading\")\n",
    "    state = checkpoints.restore_checkpoint(checkpoint, None)\n",
    "    assert \"params\" in state\n",
    "    print(\"[*] Initializing\")\n",
    "    variables = model.init(rng, init_x)\n",
    "    vars = {\n",
    "        \"params\": state[\"params\"],\n",
    "        \"cache\": variables[\"cache\"].unfreeze(),\n",
    "        \"prime\": variables[\"prime\"].unfreeze(),\n",
    "    }\n",
    "    print(\"[*] Priming\")\n",
    "    _, prime_vars = model.apply(vars, init_x, mutable=[\"prime\"])\n",
    "    return vars[\"params\"], prime_vars[\"prime\"], vars[\"cache\"]"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "cb73e418",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "Putting this altogether we can sample from a model directly."
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "32520baf",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def sample_checkpoint(path, model, length):\n",
    "    start = np.zeros((1, length, 1))\n",
    "    print(\"[*] Initializing from checkpoint %s\" % path)\n",
    "    params, prime, cache = init_from_checkpoint(model, path, start[:, :-1])\n",
    "    print(\"[*] Sampling output\")\n",
    "    return sample(model, params, prime, cache, start, 0, length - 1, rng)"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "bd47a2b3",
   "metadata": {},
   "source": [
    "### Experiments: MNIST"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "524209b9",
   "metadata": {},
   "source": [
    "Now that we have the model, we can try it out on some MNIST experiments.\n",
    "For these experiments we linearize MNIST and just treat each image as a sequence of\n",
    "pixels."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "cb9bee96",
   "metadata": {},
   "source": [
    "The first experiments we ran were on MNIST classification. While\n",
    "not in theory a hard problem, treating MNIST as a linear sequence\n",
    "classification task is a bit strange. However in practice, the model\n",
    "with $H=256$ and four layers seems to get up near 99% right away."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "e07c1505",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "A more visually interesting task is generating MNIST digits, by predicting entire\n",
    "sequences of pixels! Here, we simply feed in a sequence of pixels into the model and have it\n",
    "predict the next one like language modeling. With a little\n",
    "tweaking, we are able to get the model to an NLL of 0.52 on this\n",
    "task with size 512 and 6 layers (~2m parameters).\n",
    "\n",
    "The metric usually used for this task is *[bits per\n",
    "dimension](https://paperswithcode.com/sota/image-generation-on-mnist)* which is\n",
    "NLL in base 2 for MNIST. A score of 0.52 is ~0.76 BPD which is near PixelCNN++."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "f40067c7",
   "metadata": {},
   "source": [
    "<img src=\"images/sample.png\" width=\"100%\">"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "a5c40ccc",
   "metadata": {},
   "source": [
    "We can also do prefix-samples – given the first 300 pixels, try to complete the image.\n",
    "S4 is on the left, true on the right."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "b37f1f19",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "<img src=\"images/im0.1.png\" width=\"45%\">\n",
    "<img src=\"images/im0.2.png\" width=\"45%\">\n",
    "<img src=\"images/im0.3.png\" width=\"45%\">\n",
    "<img src=\"images/im0.4.png\" width=\"45%\">\n",
    "<img src=\"images/im0.5.png\" width=\"45%\">\n",
    "<img src=\"images/im0.6.png\" width=\"45%\">\n",
    "<img src=\"images/im0.7.png\" width=\"45%\">\n",
    "<img src=\"images/im0.8.png\" width=\"45%\">"
   ]
  },
  {
   "cell_type": "code",
   "execution_count": null,
   "id": "df607e1c",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "outputs": [],
   "source": [
    "def sample_mnist_prefix(path, model, length):\n",
    "    import matplotlib.pyplot as plt\n",
    "    import numpy as onp\n",
    "    from .data import Datasets\n",
    "\n",
    "    BATCH = 32\n",
    "    START = 300\n",
    "    start = np.zeros((BATCH, length, 1))\n",
    "    params, prime, init_cache = init_from_checkpoint(model, path, start[:, :-1])\n",
    "\n",
    "    _, testloader, _, _, _ = Datasets[\"mnist\"](bsz=BATCH)\n",
    "    it = iter(testloader)\n",
    "    for j, im in enumerate(it):\n",
    "        image = im[0].numpy()\n",
    "\n",
    "        cur = onp.array(image)\n",
    "        cur[:, START + 1 :, 0] = 0\n",
    "        cur = np.array(cur)\n",
    "\n",
    "        # Cache the first `start` inputs.\n",
    "        out, vars = model.apply(\n",
    "            {\"params\": params, \"prime\": prime, \"cache\": init_cache},\n",
    "            cur[:, np.arange(0, START)],\n",
    "            mutable=[\"cache\"],\n",
    "        )\n",
    "        cache = vars[\"cache\"].unfreeze()\n",
    "        out = sample(model, params, prime, cache, cur, START, length - 1, rng)\n",
    "        print(j)\n",
    "\n",
    "        # Visualization\n",
    "        out = out.reshape(BATCH, 28, 28)\n",
    "        final = onp.zeros((BATCH, 28, 28, 3))\n",
    "        final2 = onp.zeros((BATCH, 28, 28, 3))\n",
    "        final[:, :, :, 0] = out\n",
    "        f = final.reshape(BATCH, 28 * 28, 3)\n",
    "        i = image.reshape(BATCH, 28 * 28)\n",
    "        f[:, :START, 1] = i[:, :START]\n",
    "        f[:, :START, 2] = i[:, :START]\n",
    "        f = final2.reshape(BATCH, 28 * 28, 3)\n",
    "        f[:, :, 1] = i\n",
    "        f[:, :START, 0] = i[:, :START]\n",
    "        f[:, :START, 2] = i[:, :START]\n",
    "        for k in range(BATCH):\n",
    "            fig, (ax1, ax2) = plt.subplots(ncols=2)\n",
    "            ax1.set_title(\"Sampled\")\n",
    "            ax1.imshow(final[k] / 256.0)\n",
    "            ax2.set_title(\"True\")\n",
    "            ax1.axis(\"off\")\n",
    "            ax2.axis(\"off\")\n",
    "            ax2.imshow(final2[k] / 256.0)\n",
    "            fig.savefig(\"im%d.%d.png\" % (j, k))\n",
    "            print(j)"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "b511f44f",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "### Experiments: QuickDraw"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "e3cc7dc9",
   "metadata": {},
   "source": [
    "Next we tried training a model to generate drawings. For this we\n",
    "used the [QuickDraw\n",
    "dataset](https://github.com/googlecreativelab/quickdraw-dataset).\n",
    "The dataset includes a version of the dataset downsampled to MNIST\n",
    "size so we can use roughly the same model as above. The dataset\n",
    "is much larger though (5M images) and more complex. We only trained\n",
    "for 1 epoch with a $H=256$, 4 layer model. Still, the approach was\n",
    "able to generate relatively coherent completions. These are prefix\n",
    "samples with 500 pixels given."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "f7de13aa",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "<img src=\"images/quickdraw/im1.png\" width=\"45%\">\n",
    "<img src=\"images/quickdraw/im2.png\" width=\"45%\">\n",
    "<img src=\"images/quickdraw/im3.png\" width=\"45%\">\n",
    "<img src=\"images/quickdraw/im4.png\" width=\"45%\">\n",
    "<img src=\"images/quickdraw/im5.png\" width=\"45%\">\n",
    "<img src=\"images/quickdraw/im6.png\" width=\"45%\">"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "bf1b4918",
   "metadata": {},
   "source": [
    "### Experiments: Spoken Digits"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "590ef45a",
   "metadata": {},
   "source": [
    "Finally we played with modeling sound waves directly. For these, we\n",
    "use the\n",
    "[Free Spoken Digits Datasets](https://github.com/Jakobovski/free-spoken-digit-dataset)\n",
    "an MNIST like dataset of various speakers reading off digits. We\n",
    "first trained a classification model and found that the approach was\n",
    "able to reach $97\\%$ accuracy just from the raw soundwave. Next we\n",
    "trained a generation model to produce the sound wave directly. With\n",
    "$H=512$ the model seems to pick up the data relatively well. This\n",
    "dataset only has around 3000 examples, but the model can produce\n",
    "reasonably good (cherry-picked) continuations. Note these sequences are 6400 steps\n",
    "long at an 8kHz sampling rate, discretized to 256 classes with\n",
    "[Mu Law Encoding](https://en.wikipedia.org/wiki/%CE%9C-law_algorithm)."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "ddcd1f3c",
   "metadata": {},
   "source": [
    "<center>\n",
    "<img src='images/speech3.1.png' width='100%'>\n",
    "<audio controls>\n",
    " <source src='images/sample3.1.wav' type='audio/wav'>\n",
    "</audio>\n",
    "<audio controls>\n",
    " <source src='images/sample3.1.gold.wav' type='audio/wav'>\n",
    "</audio>\n",
    "\n",
    "<img src='images/speech6.1.png' width='100%'>\n",
    "<audio controls>\n",
    " <source src='images/sample6.1.wav' type='audio/wav'>\n",
    "</audio>\n",
    "<audio controls>\n",
    " <source src='images/sample6.1.gold.wav' type='audio/wav'>\n",
    "</audio>\n",
    "\n",
    "<img src='images/speech7.0.png' width='100%'>\n",
    "<audio controls>\n",
    " <source src='images/sample7.0.wav' type='audio/wav'>\n",
    "</audio>\n",
    "<audio controls>\n",
    " <source src='images/sample7.0.gold.wav' type='audio/wav'>\n",
    "</audio>\n",
    "\n",
    "<img src='images/speech9.0.png' width='100%'>\n",
    "<audio controls>\n",
    " <source src='images/sample9.0.wav' type='audio/wav'>\n",
    "</audio>\n",
    "<audio controls>\n",
    " <source src='images/sample9.0.gold.wav' type='audio/wav'>\n",
    "</audio>\n",
    "\n",
    "<img src='images/speech10.0.png' width='100%'>\n",
    "<audio controls>\n",
    " <source src='images/sample10.0.wav' type='audio/wav'>\n",
    "</audio>\n",
    "<audio controls>\n",
    " <source src='images/sample10.0.gold.wav' type='audio/wav'>\n",
    "</audio>\n",
    "\n",
    "<img src='images/speech13.1.png' width='100%'>\n",
    "<audio controls>\n",
    " <source src='images/sample13.1.wav' type='audio/wav'>\n",
    "</audio>\n",
    "<audio controls>\n",
    " <source src='images/sample13.1.gold.wav' type='audio/wav'>\n",
    "</audio>\n",
    "\n",
    "<img src='images/speech23.0.png' width='100%'>\n",
    "<audio controls>\n",
    " <source src='images/sample23.0.wav' type='audio/wav'>\n",
    "</audio>\n",
    "<audio controls>\n",
    " <source src='images/sample23.0.gold.wav' type='audio/wav'>\n",
    "</audio>\n",
    "\n",
    "<img src='images/speech25.0.png' width='100%'>\n",
    "<audio controls>\n",
    " <source src='images/sample25.0.wav' type='audio/wav'>\n",
    "</audio>\n",
    "<audio controls>\n",
    " <source src='images/sample25.0.gold.wav' type='audio/wav'>\n",
    "</audio>\n",
    "\n",
    "<img src='images/speech26.0.png' width='100%'>\n",
    "<audio controls>\n",
    " <source src='images/sample26.0.wav' type='audio/wav'>\n",
    "</audio>\n",
    "<audio controls>\n",
    " <source src='images/sample26.0.gold.wav' type='audio/wav'>\n",
    "</audio>\n",
    "\n",
    "<img src='images/speech26.1.png' width='100%'>\n",
    "<audio controls>\n",
    " <source src='images/sample26.1.wav' type='audio/wav'>\n",
    "</audio>\n",
    "<audio controls>\n",
    " <source src='images/sample26.1.gold.wav' type='audio/wav'>\n",
    "</audio>\n",
    "</center>"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "a79eacb6",
   "metadata": {},
   "source": [
    "Our [full code base](https://github.com/srush/annotated-s4/) contains\n",
    "more examples and infrastructure for training models for generations and\n",
    "classification."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "0d469b15",
   "metadata": {
    "lines_to_next_cell": 2
   },
   "source": [
    "## Conclusion"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "965e734b",
   "metadata": {},
   "source": [
    "Putting together this post inspired lots of thoughts about future\n",
    "work in this area. One obvious conclusion is that long-range\n",
    "models have all sorts of future applications from acoustic modeling to\n",
    "genomic sequences to trajectories (not to mention our shared area of\n",
    "NLP). Another is some surprise that linear models can be so effective\n",
    "here, while also opening up a range of efficient techniques.\n",
    "Finally from a practical level, the transformations in JAX\n",
    "make it really nice to implement complex models like this\n",
    "in a very concise way (~200 LoC), with similar efficiency and performance!"
   ]
  },
  {
   "cell_type": "markdown",
   "id": "25c8c7b2",
   "metadata": {},
   "source": [
    "We end by thanking the authors [Albert Gu](http://web.stanford.edu/~albertgu/) and\n",
    "[Karan Goel](https://krandiash.github.io/), who were super helpful in\n",
    "putting this together, and pointing you again to their\n",
    "[paper](https://arxiv.org/abs/2111.00396) and\n",
    "[codebase](https://github.com/HazyResearch/state-spaces).\n",
    "Thanks to Ankit Gupta, Ekin Akyürek, Qinsheng Zhang, Nathan Yan, and Junxiong Wang for\n",
    "contributions.\n",
    "We're also grateful for Conner Vercellino and\n",
    "Laurel Orr for providing helpful feedback on this post."
   ]
  },
  {
   "cell_type": "markdown",
   "id": "f39348c4",
   "metadata": {},
   "source": [
    "\n",
    "/ Cheers – Sasha & Sidd"
   ]
  }
 ],
 "metadata": {
  "jupytext": {
   "cell_metadata_filter": "-all",
   "main_language": "python",
   "notebook_metadata_filter": "-all"
  }
 },
 "nbformat": 4,
 "nbformat_minor": 5
}
